

By Adam Wolf
Every AI workload needs credentials: cloud storage keys, model registry tokens, database passwords, and API keys for external services. How those credentials are managed in Kubernetes determines whether they stay secret or become the entry point for a serious breach. ClearML Vaults addresses this directly by separating credential ownership from credential use at the platform level.
This is the second post in our four-part series on Kubernetes Security for Enterprise AI Environments. The series covers tenant isolation, secrets and credential management, GPU resource governance, and production model serving security.
The Credential Considerations in AI Infrastructure
An AI pipeline at scale touches a surprisingly large number of external systems. A single training pipeline might need to authenticate to an S3-compatible object store to read training data, a container registry to pull the base image, a model registry to push the trained checkpoint, a ClearML experiment tracker, a vector database for retrieval-augmented generation, and one or more third-party APIs for data enrichment or evaluation. Every one of those connections requires a credential.
In a Kubernetes environment, those credentials have to live somewhere. Where they live and how they’re accessed is one of the most consequential security decisions during AI infrastructure deployment, and one that is frequently made badly under time pressure.
Common Credential Patterns
Environment Variables in Pod Specs
The fastest way to get a credential into a running container is to put it in the pod spec as an environment variable:
yaml (the wrong way)
env:
- name: AWS_ACCESS_KEY_ID
value: "AKIAIOSFODNN7EXAMPLE"
- name: AWS_SECRET_ACCESS_KEY
value: "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY"
This is common because it is simple and works immediately. It is also dangerous for several reasons. The credential appears in plaintext in the pod spec, which means it appears in etcd (Kubernetes’ data store), any CI/CD pipeline that renders the manifest, any Git repository that stores the manifest, kubectl describe pod output visible to anyone with pod-read access, and any logging system that captures pod definitions. It’s not a secret. It’s a credential stored in the least-controlled place in the infrastructure stack.
ConfigMaps
ConfigMaps are intended for non-sensitive configuration data. They’re unencrypted by design, readable by anyone with access to the namespace, and frequently included in GitOps repositories. Using them for credentials is common enough that it appears in Kubernetes security audits as a distinct finding category.
Kubernetes Secrets (The Default, and Its Limits)
Kubernetes has a native Secrets object specifically for sensitive data. This is the correct tool compared to environment variables and ConfigMaps. But Kubernetes Secrets have important limitations that are frequently misunderstood.
By default, Kubernetes Secrets are stored in etcd encoded in base64, which is not encryption. Base64 is an encoding scheme that can be reversed in one command:
echo "d0phbHJYVXRuRkVNSS9LN01ERU5H..." | base64 --decode
Anyone with read access to etcd, or with the ability to run kubectl get secret -o yaml, can retrieve the plaintext value of any Secret in the cluster. The etcd encryption at rest feature exists and should be enabled, but it is not on by default, and it only protects against attackers who have direct access to the etcd data files, not against those operating through the Kubernetes API.
A critical misconception
Kubernetes Secrets are not encrypted by default. The name “Secret” describes the intended use, not the security properties. Without etcd encryption at rest enabled and a proper key management strategy, a Kubernetes Secret is accessible to anyone who can reach the Kubernetes API with sufficient permissions.
Beyond the storage issue, Kubernetes Secrets have no built-in access logging, no rotation mechanism, and no expiry enforcement. There is no audit trail, meaning no record of who accessed a Secret, when, from which workload, or why. Access logging tells you that a resource was read, but an audit trail tells you the full chain of custody. Kubernetes Secrets provide neither by default.
Attack Surface Map
The storage and access limitations are not isolated problems. They are entry points in a broader attack surface. Understanding where credentials are vulnerable requires mapping the full path from credential creation to credential use across every system that touches them.
| Attack vector | What's at risk | Severity |
|---|---|---|
| etcd compromise | All Secrets stored in plaintext (if encryption at rest is not enabled). Full cluster credential exposure. | Critical |
| kubectl get secret | Any user or service account with Secret-read RBAC permissions can extract plaintext values via the API. | High |
| Pod environment dump | Any process running in the container can read environment variables via /proc/. If credentials are in env vars, they're readable by any process in that pod. | High |
| Container logs | Application code that accidentally logs configuration, debug output, or error messages can expose credential values captured in log aggregation systems. | High |
| Git repository exposure | Manifests committed with hardcoded credentials, or Kubernetes Secrets exported to YAML for GitOps workflows, become permanently embedded in Git history even after deletion. | High |
| RBAC over-permission | Service accounts with broad Secret-list or Secret-get permissions can be exploited by any compromised workload running under that account to harvest all accessible credentials. | High |
| Secrets mounted as files | Secrets mounted as volumes into pods are readable by any process in the container at the mount path. Symlink attacks or file permission misconfigurations can expose them to sibling processes. | Medium |
| Credentials without expiration | Long-lived credentials (no rotation policy) extend the blast radius of any exposure indefinitely. A key leaked months ago and not rotated remains a live attack vector. | Medium |
How AI Workloads Expand Credential Scope
The credential attack surface above applies to any Kubernetes workload. AI workloads have characteristics that expand them in specific ways.
More Credentials Per Workload
A standard web application needs credentials too: a database password, container registry access, maybe cloud storage. But an AI training pipeline compounds this significantly: it needs credentials for object storage (training data), experiment tracking, model registry push access, container registry pull access, distributed training coordination services, and evaluation APIs. More credentials mean a larger attack surface and more credential sprawl to manage.
Notebooks and Interactive Environments
Data scientists frequently work in Jupyter notebooks or similar interactive environments running inside Kubernetes pods. Unlike long-lived services, these sessions are ephemeral; they spin up and tear down on demand. The challenge is that credentials need to be available inside these sessions, but storing them persistently in a way that survives session teardown without hardcoding them into images or config files requires intentional infrastructure. Without it, credentials tend to end up in the most accessible place available, which is also the least secure.
Multi-Step Pipelines Move Credentials Across Workloads
In a ClearML pipeline, a parent task orchestrates child tasks that run on different worker nodes, potentially in different environments, each step tailored to its specific role. The challenge is that credentials need to be available consistently across all of these environments. Without a centralized injection mechanism, teams end up duplicating credentials across worker configurations or baking them into stage-specific container images, each a new exposure point.
External Model Weights and Registry Access
Many AI teams pull model weights from external registries (Hugging Face Hub, NVIDIA NGC, private model stores) during training or inference. Registry authentication tokens frequently end up hardcoded in container images or pod specs because the alternative requires more infrastructure setup. This is a common source of credential exposure in AI environments.
Separating Credential Ownership from Credential Use
The fundamental principle behind secure secrets management is that the workload should not own its credentials. It should request access to them at runtime from a system that can enforce who is allowed to make that request, log every access, and revoke access independently of the workload lifecycle.
This is the principle behind dedicated secrets management systems: HashiCorp Vault, AWS Secrets Manager, Azure Key Vault, and GCP Secret Manager. Each provides centralized credential storage with access policies, audit logging, and rotation support. The Kubernetes Secrets Store CSI Driver provides a standard integration point for mounting secrets from these external systems into pods without putting the credential value in a Kubernetes Secret or environment variable.
Where ClearML Vaults Fits Into This Model
For AI teams working within ClearML, the equivalent of this separation is ClearML Vaults.
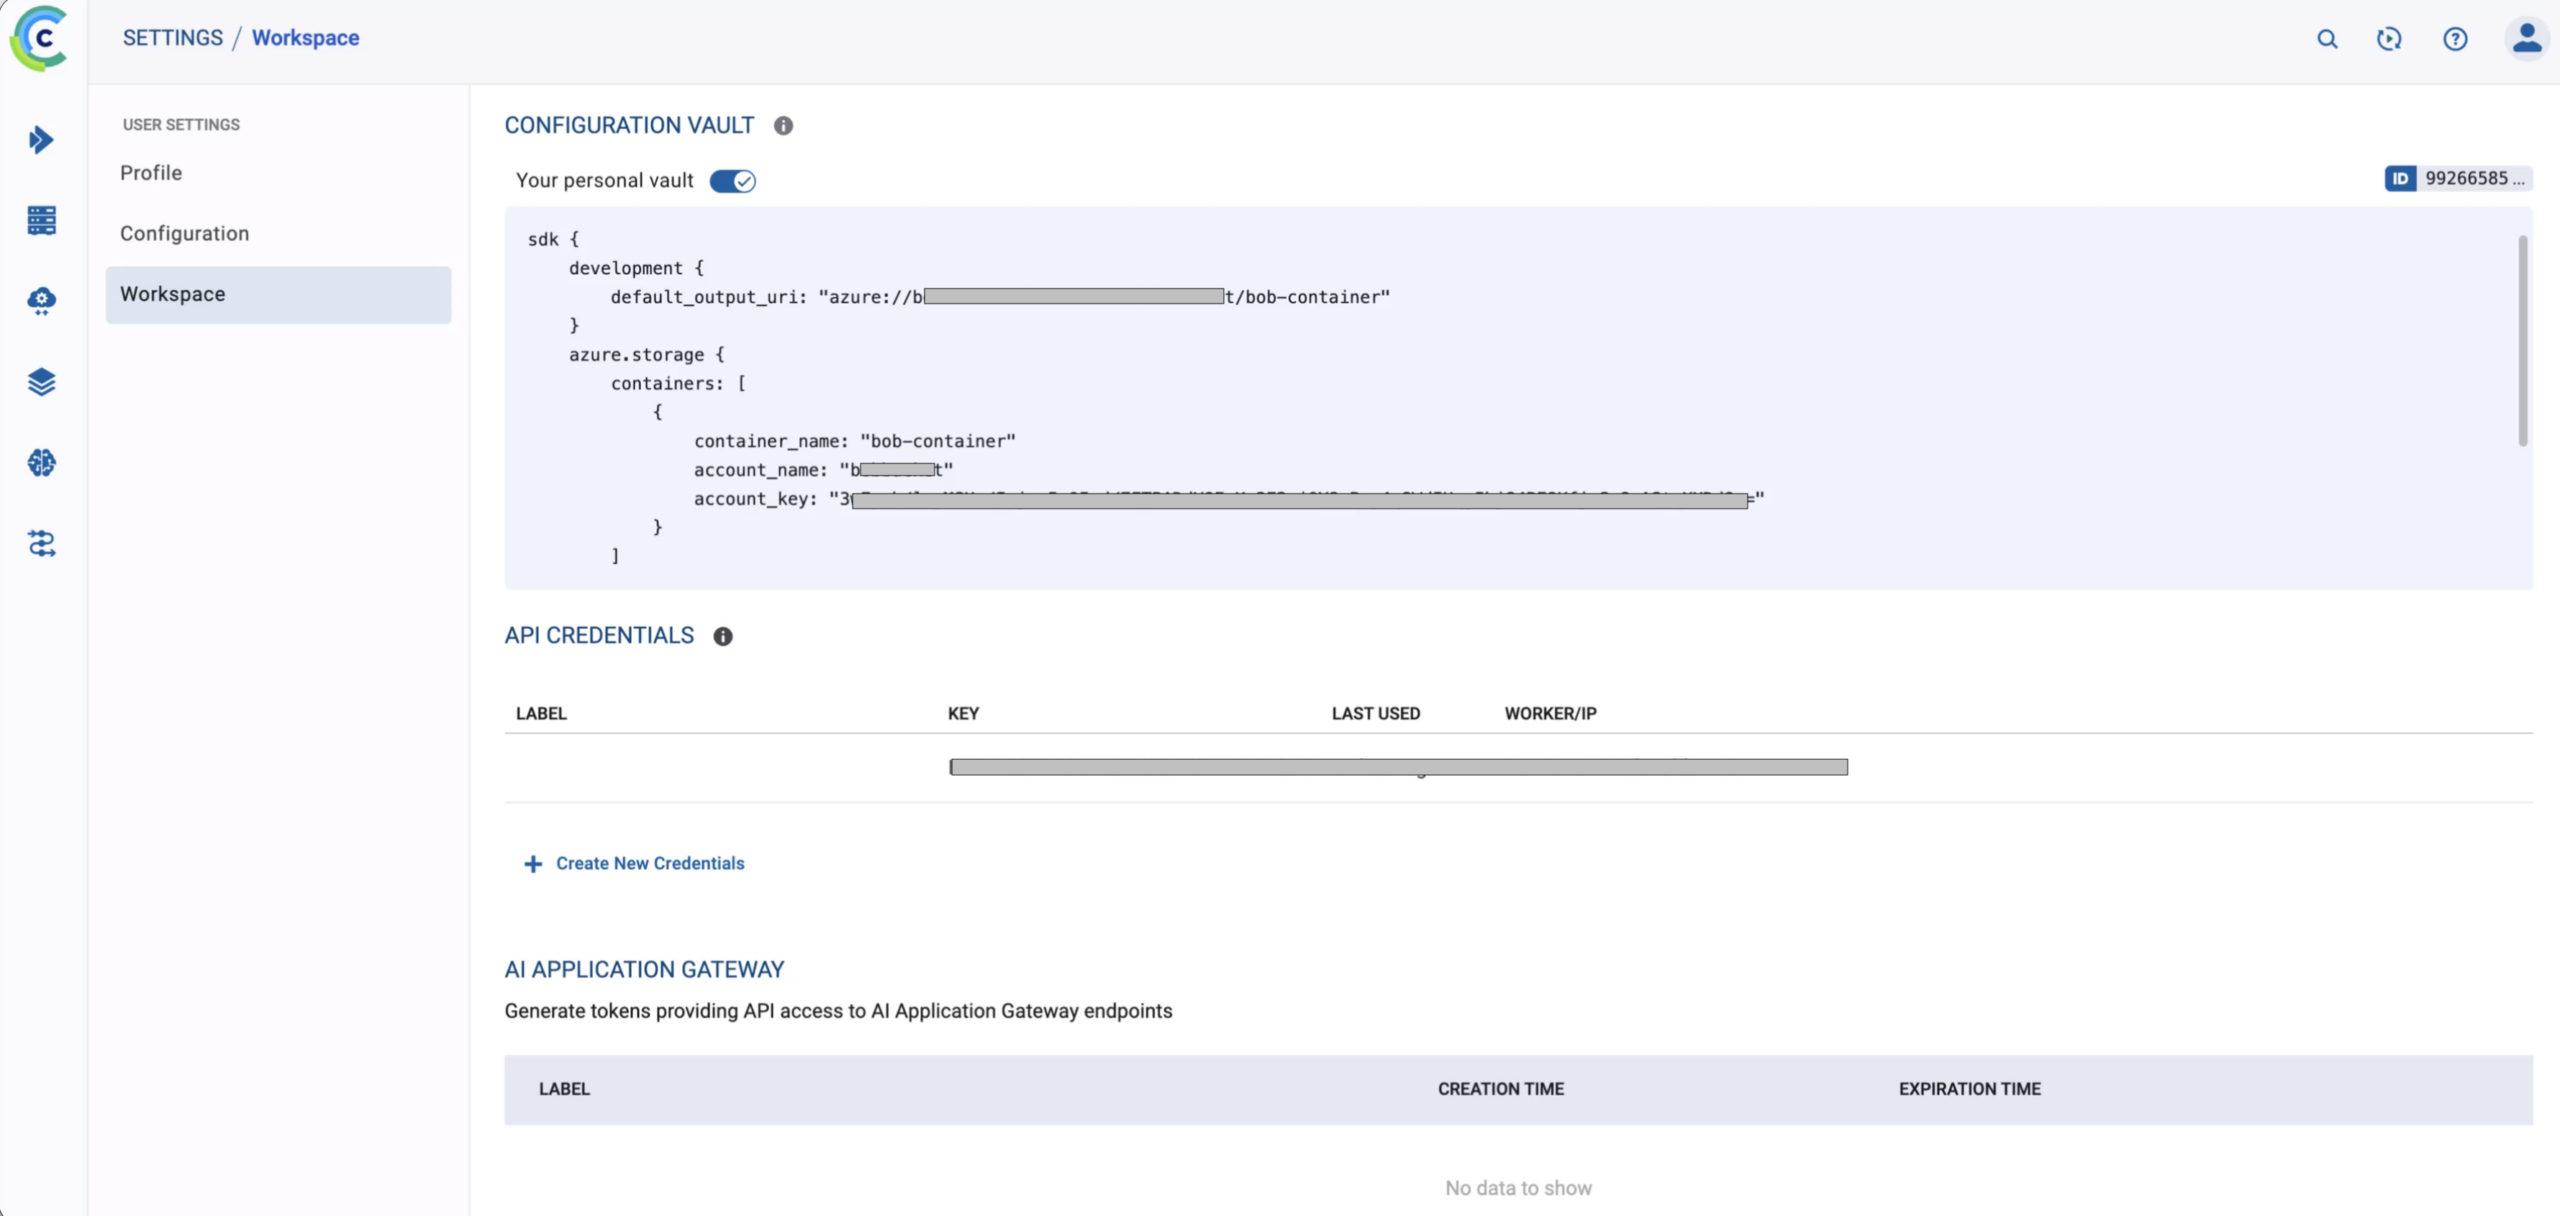
Rather than a developer embedding a cloud storage key in their experiment configuration or a pod spec, the platform team stores the credentials in a ClearML Vault. Administrator vaults apply to user groups; user vaults apply to the individual user’s own tasks. When a ClearML task runs that falls within that scope, ClearML injects the vault’s contents as environment variables into the worker environment at task execution time, without the developer ever seeing or handling the raw credential value.
This means:
- Developers write code that expects credentials to be available as environment variables, without hardcoding the values or including them in their experiment configuration
- The credential values never appear in task parameters, pipeline definitions, Git repositories, or logs
- Access to credentials is governed by ClearML’s user and group model, not by who happens to have
kubectl get secretaccess to the right namespace - The platform team can update or rotate a credential in the vault without touching any workload configuration
Vault Types
ClearML has two vault types that serve different purposes and different audiences.
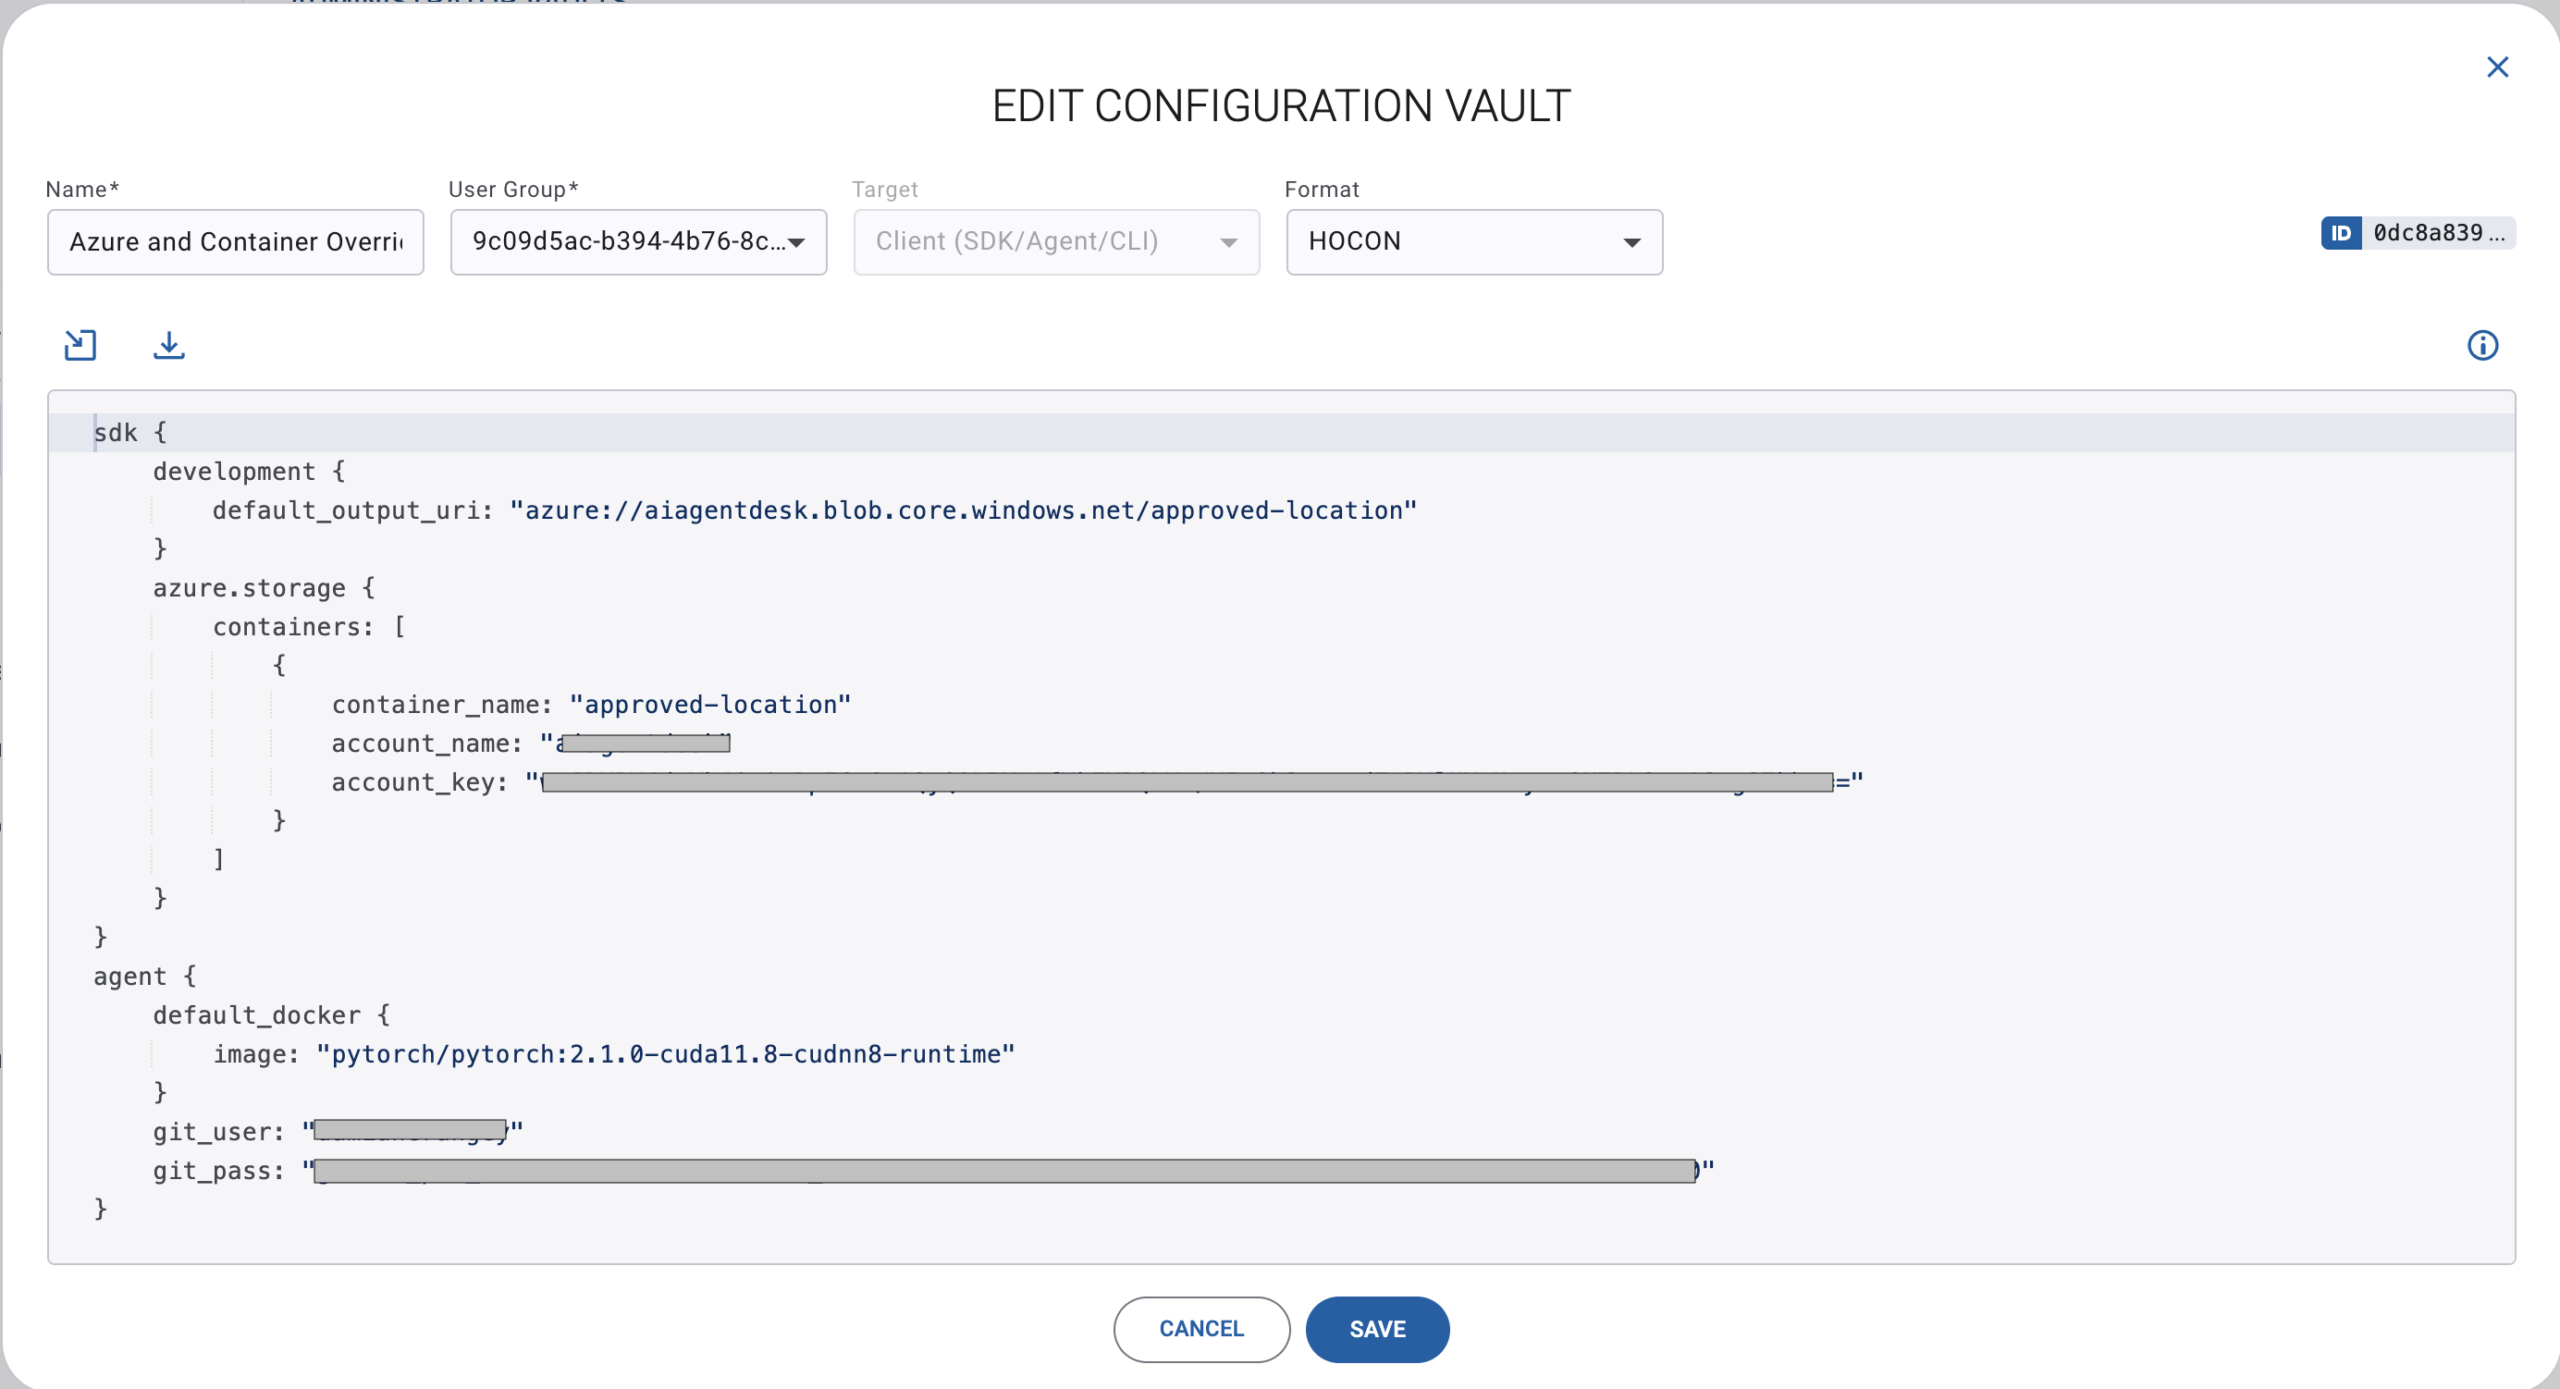
Administrator Vaults are configured by platform admins and scoped to user groups. They inject configuration values, including credentials, but also agent configuration, storage settings, and SSH keys, into any task run by members of the designated group. Administrators never need to share the values directly with users; the vault applies automatically at task execution time. There are three types of administrator vaults: client configuration (extending the ClearML agent/SDK config), UI storage credentials, and SSH server vaults.
User Vaults are personal configuration vaults each user controls in their own settings. They extend the ClearML configuration file for any agents or SDK running under that user’s credentials (useful for personal storage credentials or user-specific configuration overrides).
Both vault types hold configuration values in ClearML-supported formats (HOCON, JSON, or YAML), not raw secret strings in the traditional secrets-manager sense. Credentials are one use case (storing an S3 key or a registry token), but the vault is a general-purpose configuration injection mechanism. Values are stored encrypted on the ClearML server and injected at task runtime, never surfacing in task parameters, logs, or pipeline definitions. This separation has a practical consequence worth making explicit: a user can be granted access to a storage bucket or external service through a vault without ever seeing the credentials that enable that access. A platform admin can give a team access to a shared image dataset stored in S3, for example, without exposing the access key, which might also grant access to other buckets the team has no business reaching. The vault enforces what the user can do, not what they can see.
The Scope Model
Administrator vaults are scoped to user groups. A vault scoped to the “Data Engineering” group injects its configuration into any ClearML task run by a member of that group, without that user ever seeing the underlying values. User vaults apply to the individual user’s own tasks. This two-level model means platform teams control environment configuration at the group level, while users can layer their own personal configuration on top, and neither layer requires per-workload credential management
Layered Defenses: ClearML and Kubernetes Working Together
ClearML Vaults handles credential injection for tasks running through the platform. But a production-grade secrets posture also requires hardening the Kubernetes layer underneath. The following controls work alongside ClearML, not as an alternative to it, serving as the infrastructure foundation that ClearML sits on.
Enable etcd Encryption at Rest
If you’re using Kubernetes Secrets at all (even as an intermediate storage layer), enable encryption at rest for the Secrets resource type. This protects against attackers who gain direct access to etcd storage. Use the aescbc or secretbox providers with a key stored outside the cluster, or integrate with a KMS provider.
Restrict Secret Access via RBAC
Audit which service accounts and users have get or list access to Secrets. Most workloads should be able to access only the specific Secrets they need, not list all Secrets in a namespace. Use least-privilege RBAC with explicitly named Secret resources rather than wildcard access.
Avoid List Permissions on Secrets
The list verb on Secrets is particularly dangerous: it allows enumeration of all Secret names and metadata in a namespace, providing an attacker with a map of what credentials exist. Most legitimate workloads have no need to list Secrets; they need to read a specific named Secret. Audit for and remove list access on Secrets wherever it is not strictly necessary.
Rotate Credentials Regularly
Long-lived credentials that were exposed months ago and never rotated remain active attack vectors. Establish rotation policies for all credentials used in AI workloads. Where possible, use short-lived credentials with automatic refresh (IAM role-based access in cloud environments, Workload Identity on GKE, IRSA on EKS) rather than static API keys.
Audit Secret Access
Enable Kubernetes audit logging with a policy that captures Secret access events. A Secret that is accessed outside of normal working hours, from an unexpected service account, or at an unusual rate is an early indicator of credential harvesting. Without audit logging, you won’t know it happened.
The thread running through this post is separation: credential ownership separated from credential use, storage separated from access, what a workload can do separated from what secrets it can see. That separation is what makes a breach containable. A workload that can’t see its own credentials can’t leak them. A namespace that can’t list secrets can’t harvest them. Build the separation in, and the blast radius of any individual compromise shrinks accordingly. In the next post, we apply the same principle to compute: separating who can request GPUs from who can exhaust the pool.
Get in touch if you would like to discuss how ClearML can support your organization’s AI security requirements.