

By Adam Wolf and Damian Erangey
The previous posts in this series built the security model layer by layer: identity, configuration governance, service account automation, compute policies, and production model serving. This final post covers what holds all of it together: the monitoring and audit layer that records every action, every API call, and every resource event and makes the full picture visible to the people responsible for it. It accompanies our Enterprise AI Infrastructure Security YouTube series. Watch the corresponding video below.
Infrastructure Visibility: The Orchestration Dashboard
Every compute resource on the platform is visible through the Orchestration Dashboard. This is an Enterprise feature and the operational starting point for anyone responsible for the infrastructure underneath your AI workloads. The dashboard is organized across four tabs, each answering a different question about the state of the fleet.
Dashboard and Resource Graph
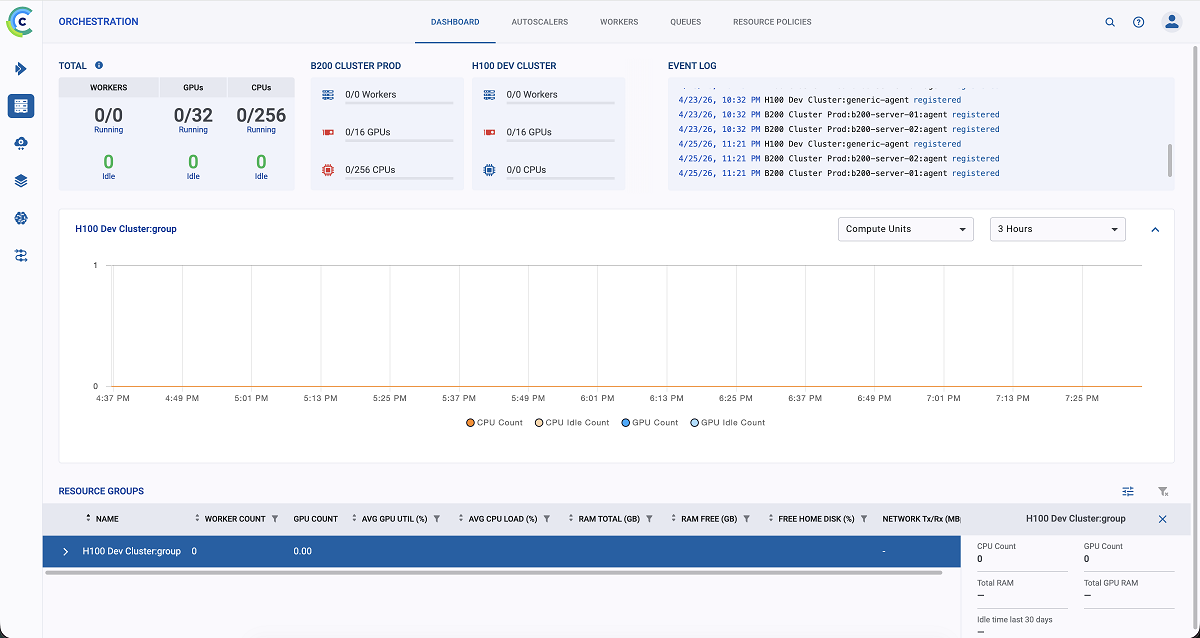
The Dashboard tab shows current resource availability and utilization counts across your entire managed environment. The Total section at the top shows aggregate GPU, CPU, and worker counts: how many are provisioned, how many are currently running, and how many are idle. These counts are also broken out per worker category, so you can see utilization by team or environment at a glance.
The Resource Graph plots utilization over time. Clicking into any specific resource group in the Resource Groups table filters the graph to that group alone, with a metric dropdown that lets you switch between Compute Units, Compute Utilization, Available Memory, Free Home Storage, and Network Throughput. You can drill from an aggregate fleet picture down to a specific group in two clicks.
The Event Log records every fleet change: workers added, workers removed, transitions from idle to busy. It is downloadable, timestamped, and functions as the infrastructure-layer audit record.
Autoscalers
The Autoscalers tab is available under the ClearML Pro plan and provides access to cloud autoscaling applications for AWS and GCP. Once an autoscaler instance is running, you can monitor its activity and cloud usage through its instance dashboard, including running instances by compute resource type, resource queue task counts, and total uptime by instance type. Cumulative uptime by instance type is directly useful for cost tracking and understanding which instance types your workloads are actually consuming.
Workers and Queues
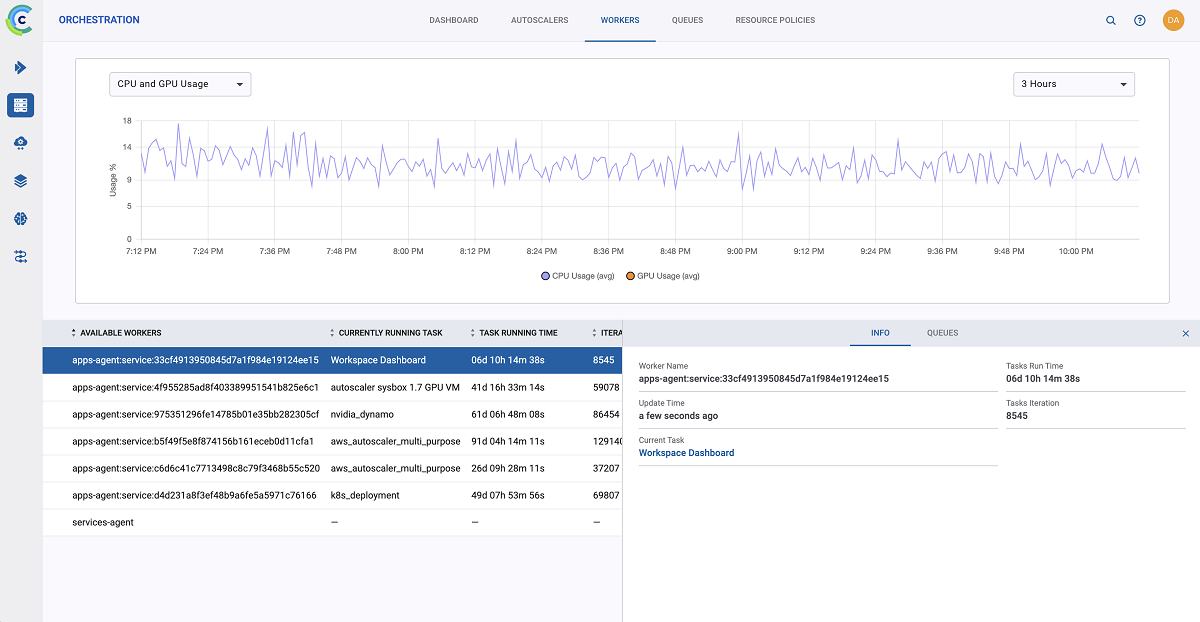
The Workers tab provides the drill-down from fleet overview to individual worker. The worker table lists every currently available worker, the task it is currently running, how long it has been running, and the current training iteration. Clicking any worker opens its details panel, replacing the graph with that worker’s resource utilization over time. You can select between CPU and GPU Usage, Memory Usage, Video Memory Usage, and Network Usage. The details panel also shows the current task, how long it has been running, and the last reported training iteration.
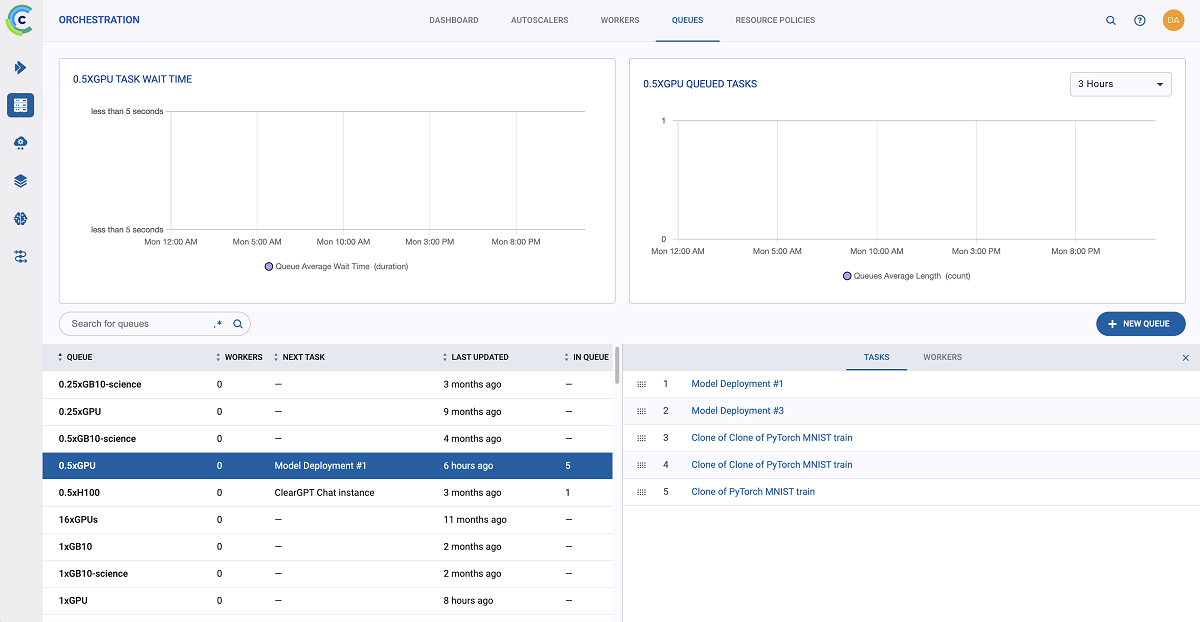
The Queues tab is where you monitor whether user-submitted tasks are flowing as expected into your compute resources. Two graphs show average task wait time and the number of queued tasks per queue over time. Wait time tells you whether jobs are being picked up. Queue length tells you whether work is backing up. Below the graphs, the queue table lists every queue on the platform with worker count, next task, and the number of tasks currently enqueued. This is where you see the resource pools, profiles, and policies from the compute governance post in action. The policy configuration is what created these queues, and this is where you observe them running.
Projects and Tasks: The Governance and Audit Boundary
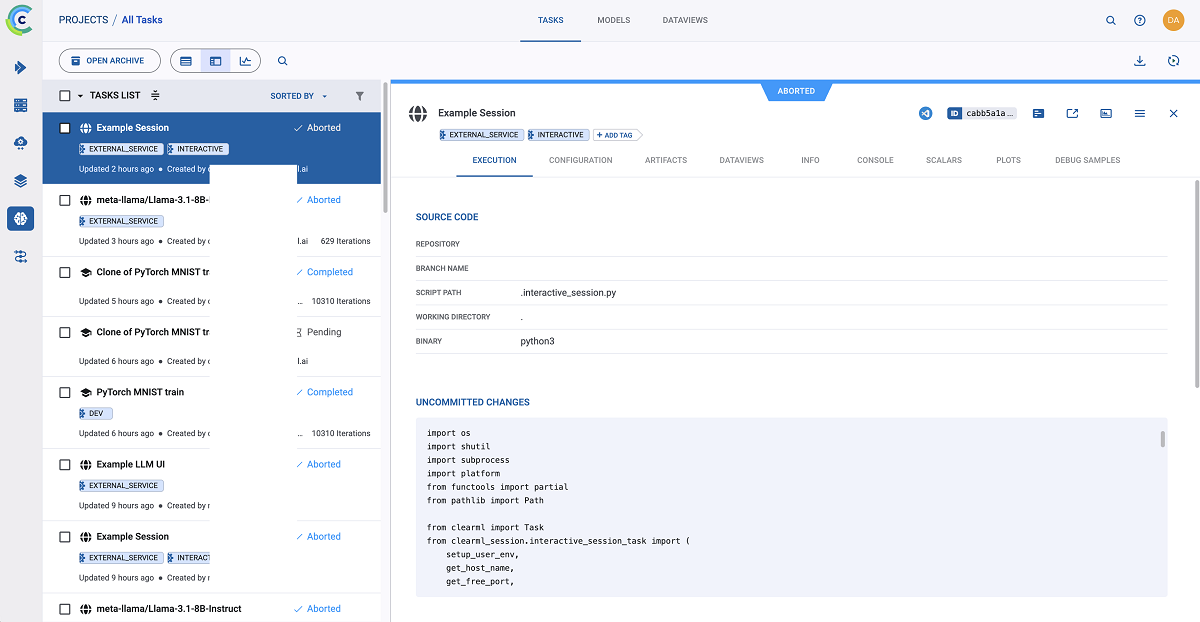
Everything on the platform is a task, and tasks are organized by projects. The Projects page is where your cost and governance boundaries are drawn. The access rules from the identity post all anchor to projects. Who can see what is determined at the project level.
The All Tasks view provides a cross-project task list, filterable and exportable. Models and Dataviews are also accessible globally. For listing, filtering, and exporting metadata across the entire platform, this is the single place to go.
Project Overview and Workloads
The Project Overview tab is a configurable metric snapshot across all tasks in the project. For a training project, that might be loss curves over time. For a serving project, it might be token and request counts. It is a quick configurable summary of what the project is doing, not a deep audit surface. That comes from the other tabs.
The Workloads tab is where cost and activity attribution happen at the project level. It surfaces task execution telemetry broken down in three ways: by Resource (the queue tasks were executed through), by Project, and by User (the task owner). For each breakdown it shows daily execution time over the period and the period total. This is the data that feeds showback and chargeback at the project level. It is a precise record of who ran what and through which compute resource, giving teams full visibility into their consumption and enabling accurate cost attribution across the organization.
Task-Level Audit: Metadata, Logs, and Lineage
The task table is the execution history for any project. Every task that has ever run is listed, and the list itself is exportable as a CSV with type, name, tags, status, project, and user for every entry. That export is directly useful for access reviews, chargeback reconciliation, and compliance reporting.
Info Tab: Task Metadata and Event Log
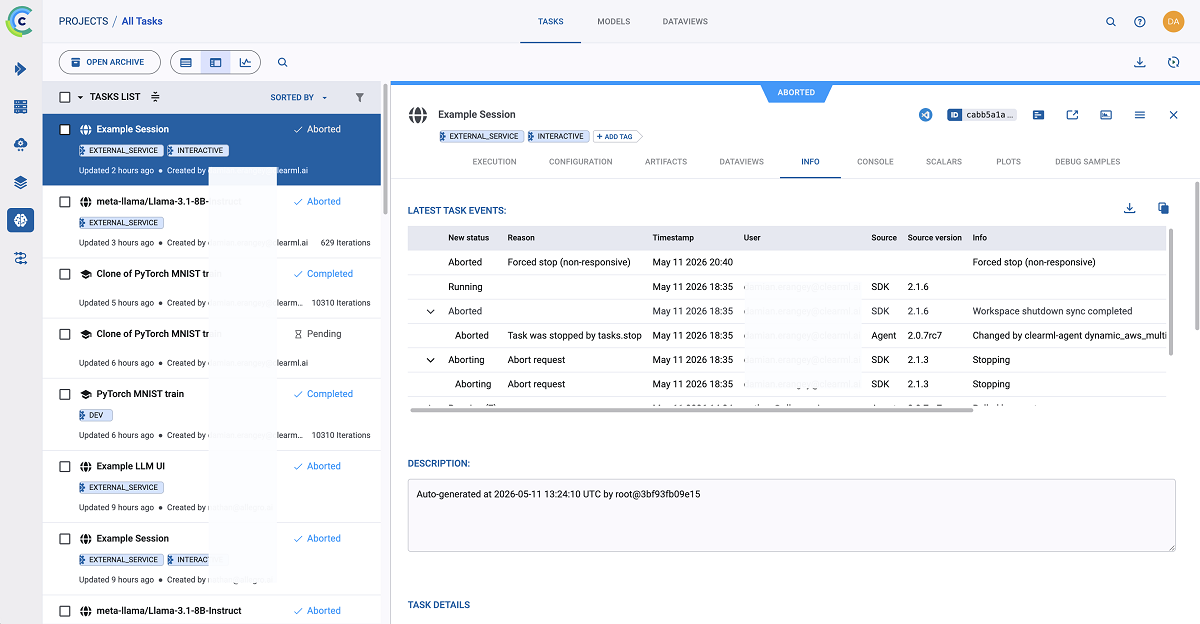
Inside any task, the Info tab includes the latest events log, task description, and task details. The events log is available on the ClearML Hosted Service and Enterprise plan and records a detailed history of task activity: each task action (such as status changes or project moves), the action time, the acting user, and the action source (ClearML Agent, SDK, or UI). The log is downloadable as a CSV. The Task Details section lists the parent task, project name, creation, start, and last update times, the user who created the task, and task status.
Console Tab: Permanent Execution Record
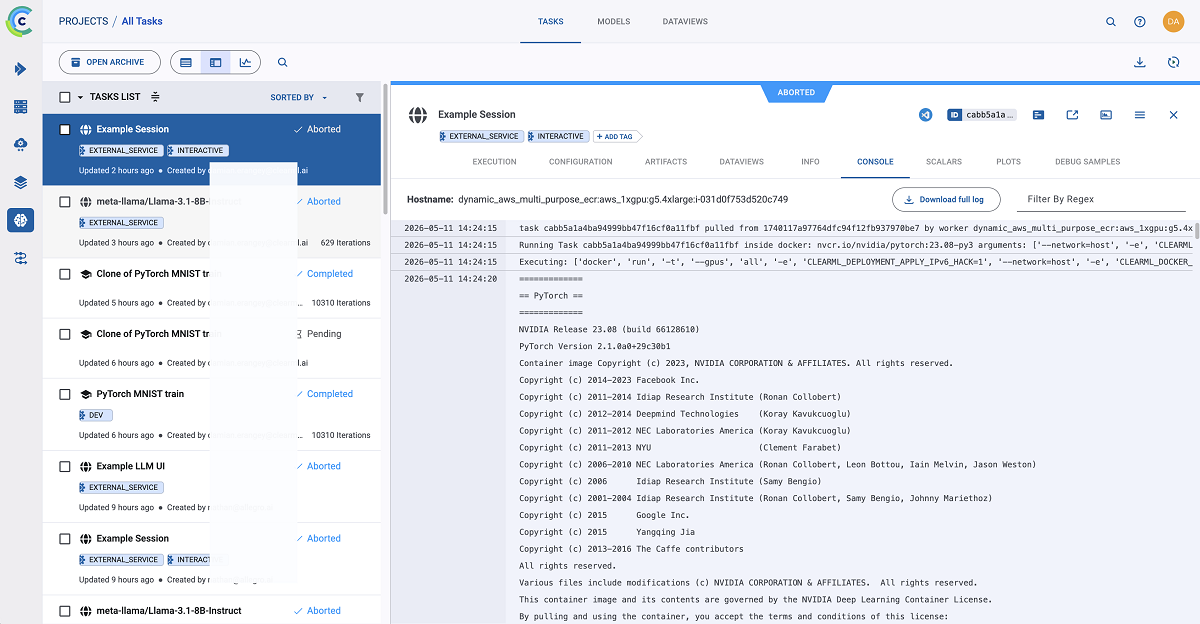
The Console tab captures the full standard output and standard error of the task as it ran. You can download the complete log as a file with a single click. For a long-running service endpoint, that means a permanent, auditable record of what the service was actually doing, independent of the container that ran it, even after the pod is recycled. The log persists on the platform regardless of the underlying infrastructure state.
Execution Tab: Environment Capture
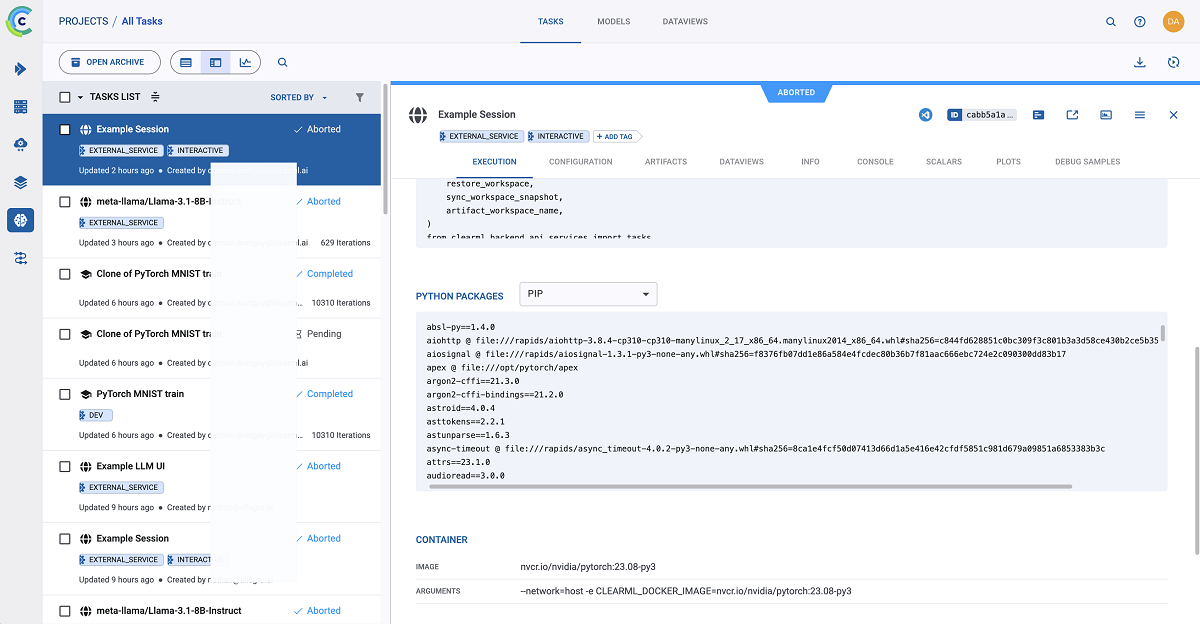
The Execution tab captures the full environment automatically: source code repository, commit ID, uncommitted changes, installed Python packages, and container details (image, arguments, and setup script). This is the reproducibility record. Everything needed to understand exactly what code ran and in what environment is captured at execution time without any manual instrumentation.
Model Lineage
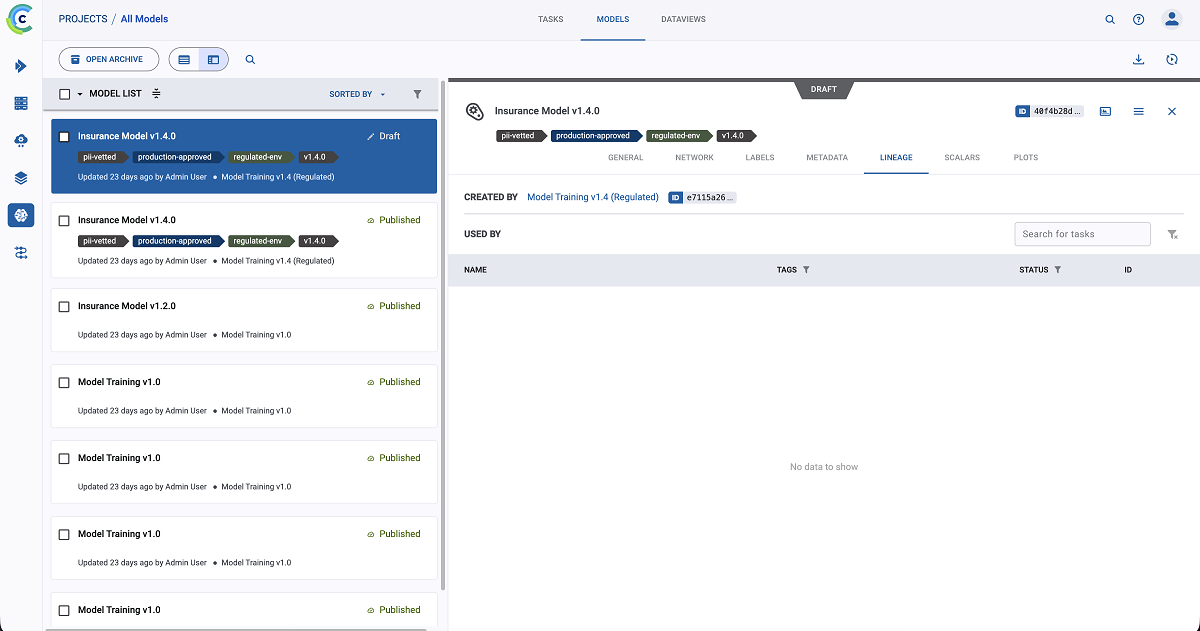
The Models tab for any project lists every registered model with framework, status, model ID, and the user who created it. The field that matters for audit is “Created by task ID.” Every model links back to the task that produced it, and clicking through to the model opens dedicated tabs for Lineage, Metadata, Scalars, and Plots that preserve the full chain from training run to registered artifact. When an auditor asks which run produced a given model, the answer is one click away.
Model Serving: Endpoint Monitoring
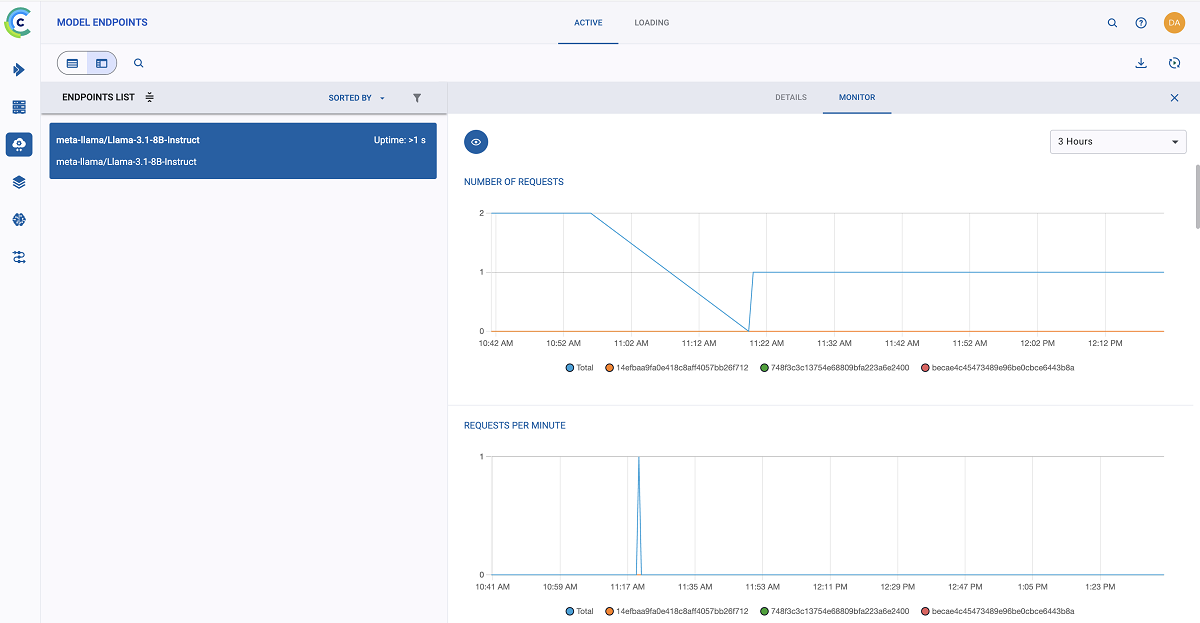
Every model deployed through the ClearML Deploy UI applications appears in the Model Endpoints page, giving you a unified, platform-wide view of all active endpoints.
The endpoint table shows every currently active endpoint with its name, model, URL, number of instances, uptime, total request count, average requests per minute, and average latency. Clicking any endpoint opens its detailed view. The Details tab shows the endpoint name and URL, the model being served with a link to its model page, uptime, and the Model Instances list. For each instance behind the endpoint, you get the instance ID, uptime, total request count, request rate, CPU count, GPU count, and average latency.
The Monitor tab provides the live operational picture. On the activity side: total number of requests, average requests per minute, and average latency. On the infrastructure side: CPU and GPU usage, memory usage, video memory usage, and network usage. All metrics are scoped to the specific endpoint and plotted over time.
Every endpoint is backed by a ClearML application, and every application is backed by a task. If the Monitor tab is not sufficient, you can drill through to the application instance dashboard for live console logs and from there to the underlying task for the full audit surface covered above.
The Pattern Applies to Every Application
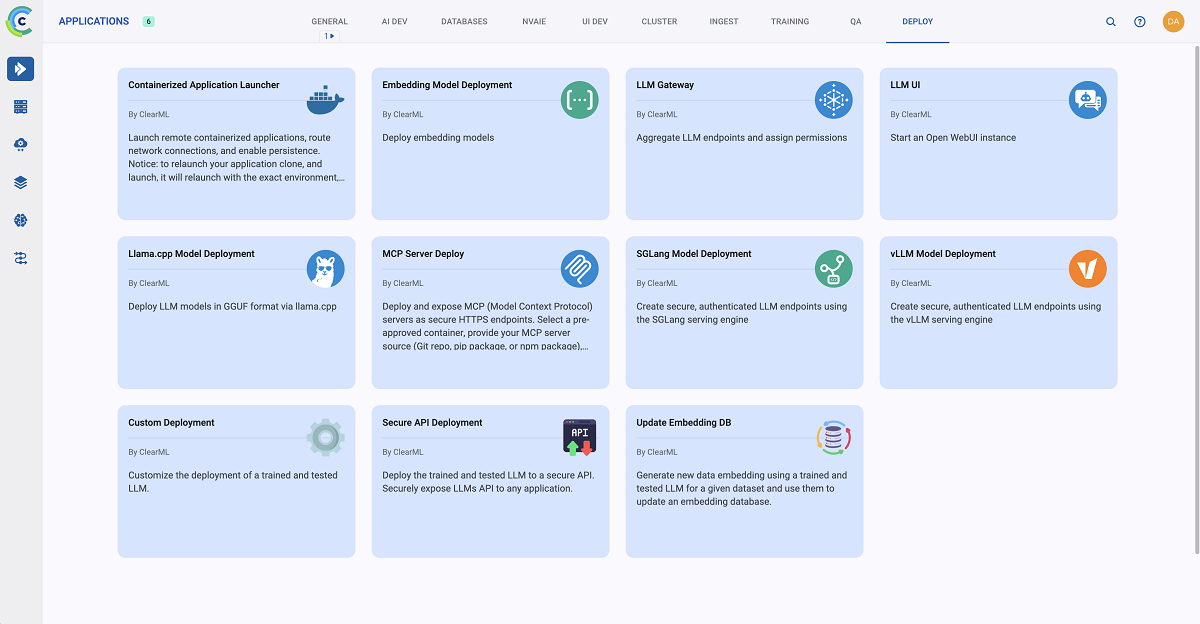
The vLLM deployment is one example. Every application on the platform runs as a ClearML task, which means all of them inherit the same monitoring and audit pattern: an instance dashboard with application-specific graphs, a downloadable console log, and the underlying task view with the full Info and Execution audit surface. This applies equally to SGLang, Llama.cpp, NVIDIA NIM containers, Gradio Launcher, Streamlit Launcher, JupyterLab, VS Code, and SSH Sessions.
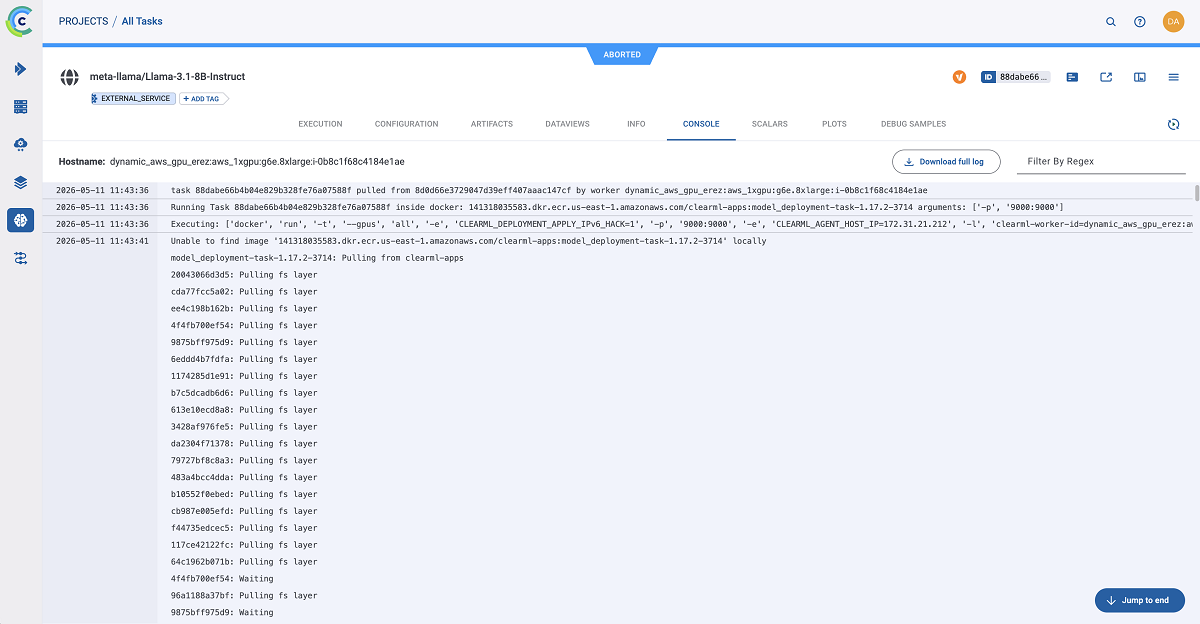
The security model does not change based on the workload type. The same audit trail applies to a Jupyter session as to a production LLM endpoint.
Cost Attribution and Showback
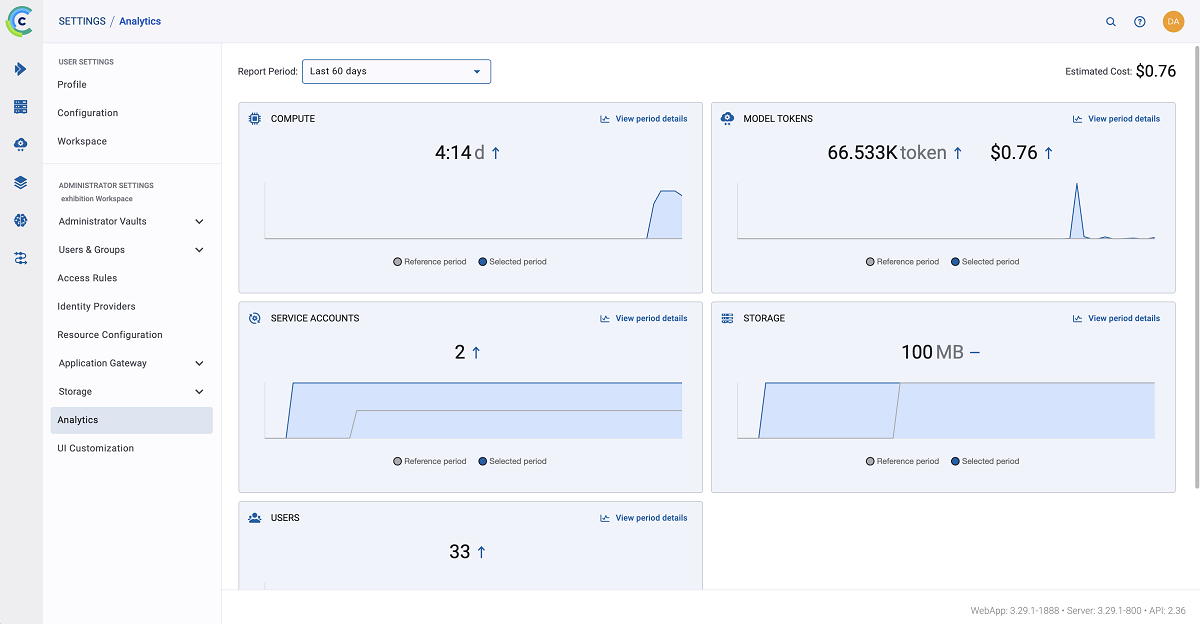
The Analytics dashboard provides cost attribution across the workspace. At the top, an estimated cost for the selected period. Below that, four cost categories: Compute, Users, Storage, and Service Accounts. Each shows the period total, estimated cost, trend versus the comparative period, and a trajectory sparkline. Each category has a “View period details” link that drills into the breakdown: which users, which compute pools, and which projects consumed what.
That drill-down is what turns a top-line cost number into showback or chargeback per team. The data exists at the task level through the Workloads tab and at the workspace level through Analytics. Organizations can pull the same data programmatically through the REST API and feed it into their existing chargeback systems.
Platform Management: Cross-Tenant Visibility
For organizations running ClearML as a service for multiple business units or cloud service providers hosting multiple customer tenants, the Platform Management Center provides cost and usage visibility rolled up to the platform level. It gives real-time visibility into compute hours, storage, and token usage across every tenant on the platform, feeding the same showback and chargeback workflows as Analytics but at the platform level rather than the tenant or workspace level.
The key property for IT and compliance: administrators see consumption numbers, not workloads. Tenant isolation is preserved. You get platform-level observability without access to what is running inside any individual tenant, which is what regulated industries and multi-customer deployments need.
User Activity and Platform Integration
Users Table
The Users table is the reference point for human activity on the platform. For every workspace member, ClearML tracks name, email, unique user ID, last API token generation, and last UI activity. The table is exportable and accessible through the REST API, so it can be pulled into whatever identity governance tooling the organization already uses.
This table is most useful for investigation. A SIEM alert flags unusual API activity. A cost spike triggers a review. The Users table is where you verify what is actually happening on the platform. Last API token generation tells you when credentials were last issued. Last UI activity tells you when the account was last used. Together they give you the information needed to determine whether activity is expected or anomalous.
REST API and External Integration
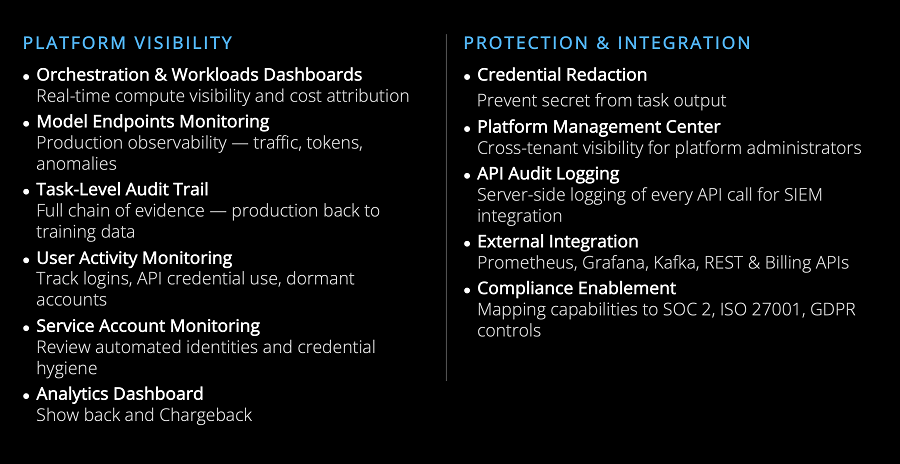
Everything visible in the GUI is accessible programmatically through the ClearML REST API. That means every monitoring and audit feature covered in this post can be integrated into whatever stack the organization is already running: SIEM tools, Grafana dashboards, Slack alerting, and chargeback systems. Three integration layers are worth calling out specifically:
- SIEM integration: task event logs, user activity records, and API token usage data are all accessible via REST and can be streamed to any SIEM that accepts HTTP-based ingestion.
- Observability stacks: the same infrastructure metrics available in the Orchestration Dashboard (CPU, GPU, memory, and network per resource group) are accessible programmatically for feeding into Grafana, Datadog, or any metrics aggregation layer.
- Chargeback systems: execution time consumption by user, project, and service account can be pulled through the API on any cadence and fed into existing financial reporting or cost allocation systems.
How This Maps to Compliance Controls
The audit trail described in this post is not a separate compliance layer built on top of the platform. It is the operational layer, which happens to satisfy compliance requirements by design. The controls that security and compliance teams most commonly need to demonstrate are covered without additional configuration:
- Access reviews: the task table CSV export gives you a user-tagged list of every execution across every project. The Users table gives you last-activity timestamps for every account. Together they provide the data needed for periodic access reviews without manual collection.
- Credential governance: last API token generation is tracked per user in the Users table, and administrator vaults ensure credentials injected at runtime are never exposed in plain text in logs.
- Workload attribution: every task records its creator, creation time, triggering mechanism (agent, SDK, or UI), and the full execution environment. Every model links back to the task that produced it. Every endpoint links back to the model and the application instance that serves it. The chain from data to model to live endpoint is traceable in full.
- Tenant isolation assurance: the Platform Management Center provides cross-tenant consumption visibility while enforcing that administrators cannot access workload contents within any individual tenant. The isolation is structural, not policy-based.
- Incident investigation: console logs persist independent of container lifecycle. Event logs capture every state transition with the triggering user and mechanism. API token activity is tracked per user. When something goes wrong, the record is there.
Closing
This post is the seventh and final entry in ClearML’s Enterprise AI Security series. Over the course of the series, six layers of the security model have been covered: identity flowing through your existing IdP, credentials living in administrator vaults rather than in code, service accounts with the same access controls as human users, compute access that is policy-driven and quota-enforced, model endpoints behind an authenticated gateway, and an audit and monitoring layer that captures every action, every API call, and every resource event, exportable and ready for integration into your existing infrastructure.
Each layer reinforces the others. The identity layer makes every action attributable. The vault layer ensures credentials never appear in logs. The service account layer extends governance to automated workloads. The compute policy layer makes resource consumption auditable. The gateway layer makes endpoint access traceable. And the monitoring layer captures all of it, persistently, in a form that compliance and operations teams can use.
The result is an AI platform that is governable without being a bottleneck, one where security is a property of the architecture rather than an overhead applied on top of it.
Learn More
Find the full Enterprise AI Security video series on YouTube. Get in touch if you would like to discuss how ClearML can support your organization’s AI infrastructure security and compliance requirements.